How many GPUs for my launch?
An API provider launching DeepSeek-V3 for five kinds of work, about 690 requests a second at the busiest hour. The Capacity Planner sizes it on two H200 clusters: 264 GPUs, every promise met.
Capacity Planner / demo 1
01What you enter, what you get
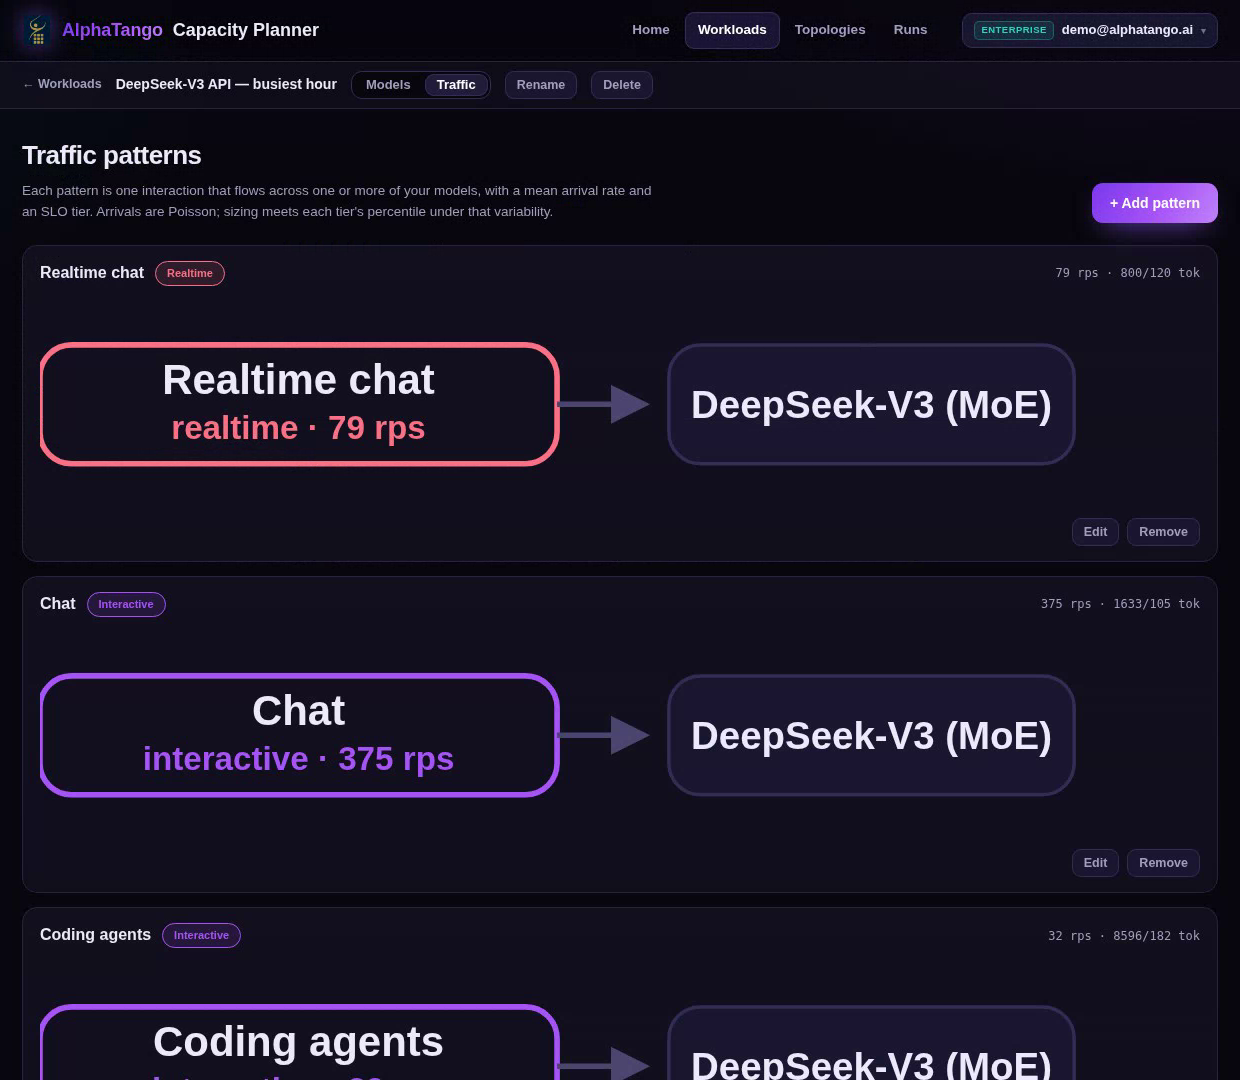
Five kinds of request on DeepSeek-V3 (realtime chat, chat, coding agents, reasoning and batch), 687 requests a second at the busiest hour, each with its speed promise. Two clusters of NVIDIA H200s joined by an 800 Gb/s fabric.
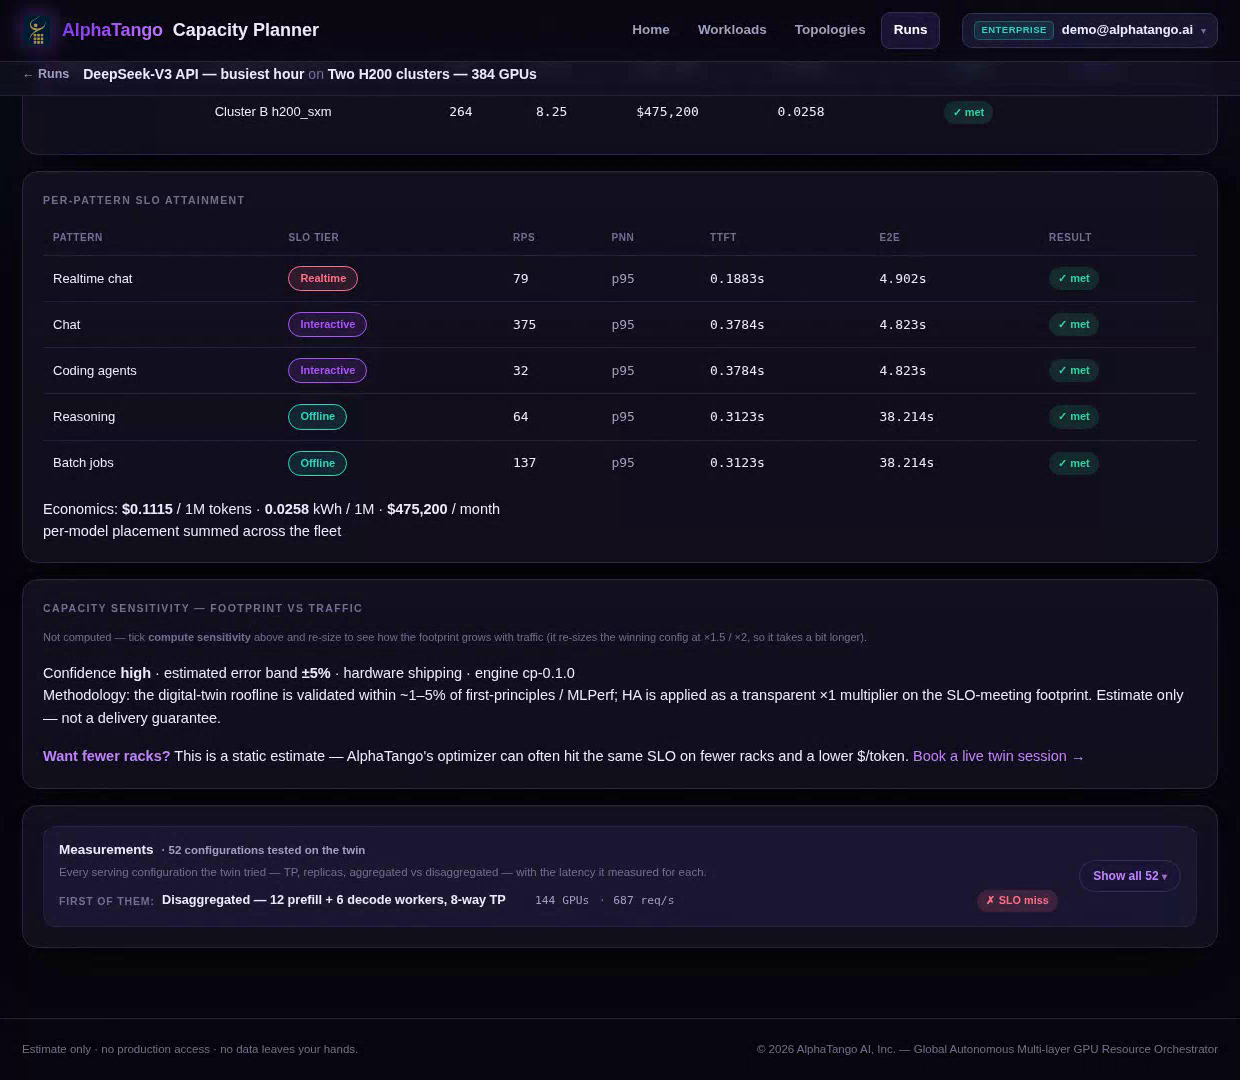
264 GPUs: 33 copies of the model, 8 GPUs each, 192 on the first cluster and 72 on the second. Every speed promise met: realtime chat's first word in 0.19 s (promise 0.5 s). About $475,200 a month at rental prices, 153 kW.
02The Capacity Planner's report
Every run produces a report you can share: the workload, the recommended cluster, each traffic pattern against its speed promise, and the economics. This is the summary report from this demo, exactly as the Capacity Planner produced it.

03Watch
The demo in 38 seconds.
The real Capacity Planner screens, sped up.