What does reliability cost?
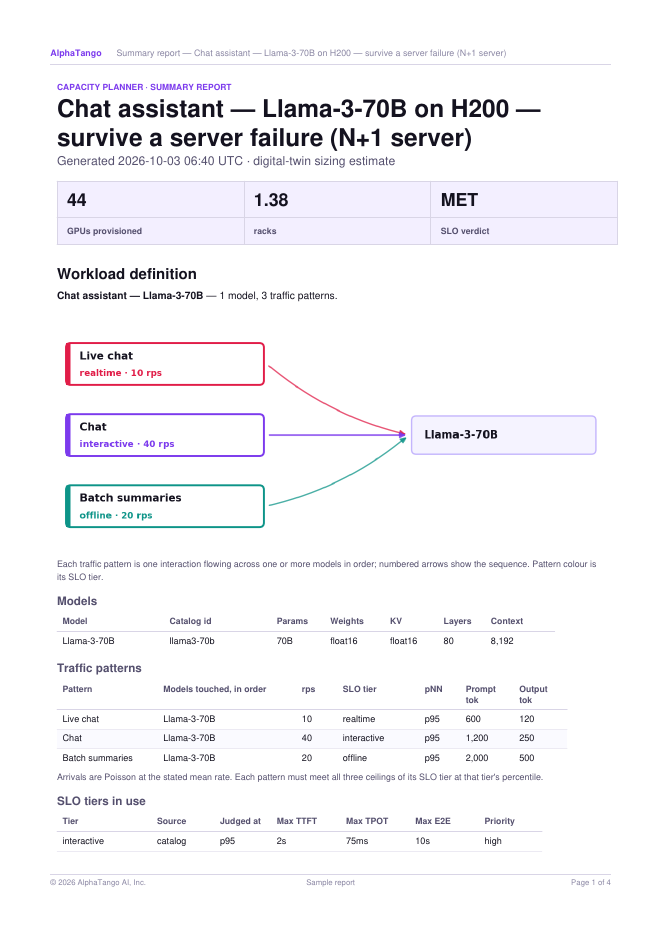
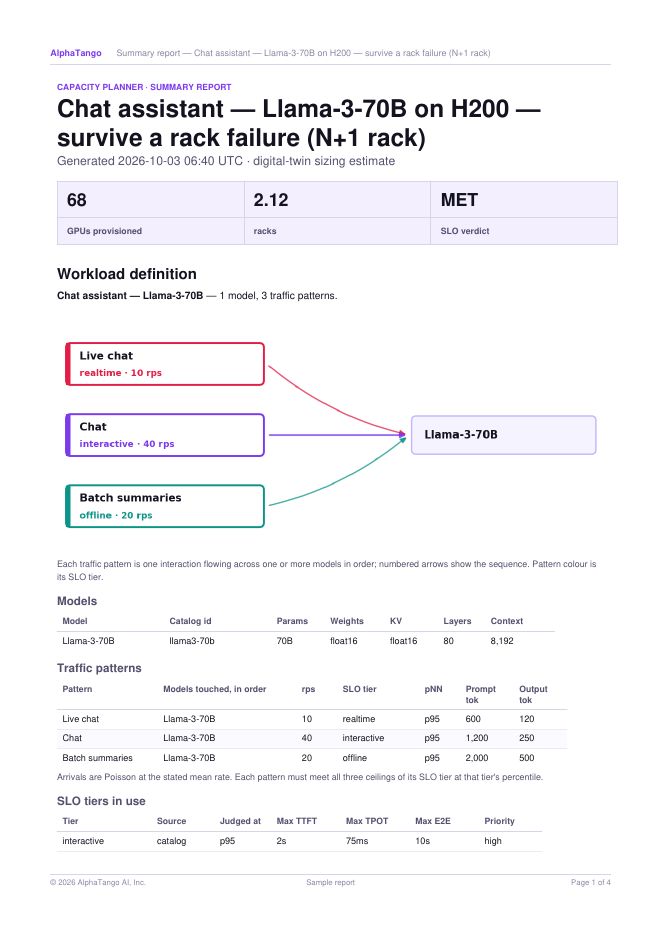
The Llama-3-70B chat assistant needs 32 H200 GPUs, $57,600 a month. Surviving a server failure takes 44 GPUs ($79,200); surviving a whole rack failing takes 68 ($122,400). Know the price of each promise.
Capacity Planner / demo 5
01What you enter, what you get
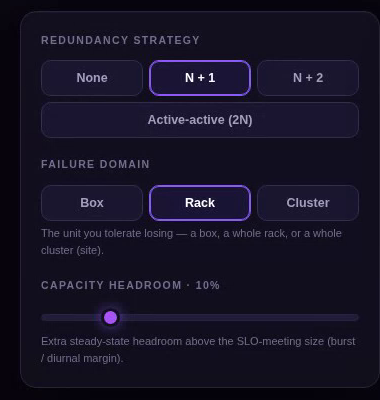
The same Llama-3-70B chat assistant as demo 2 (live chat, chat and batch summaries, 70 requests a second) on DGX H200 racks, with two availability settings: N+1 against a server failure and N+1 against a whole-rack failure, each with 10% headroom.
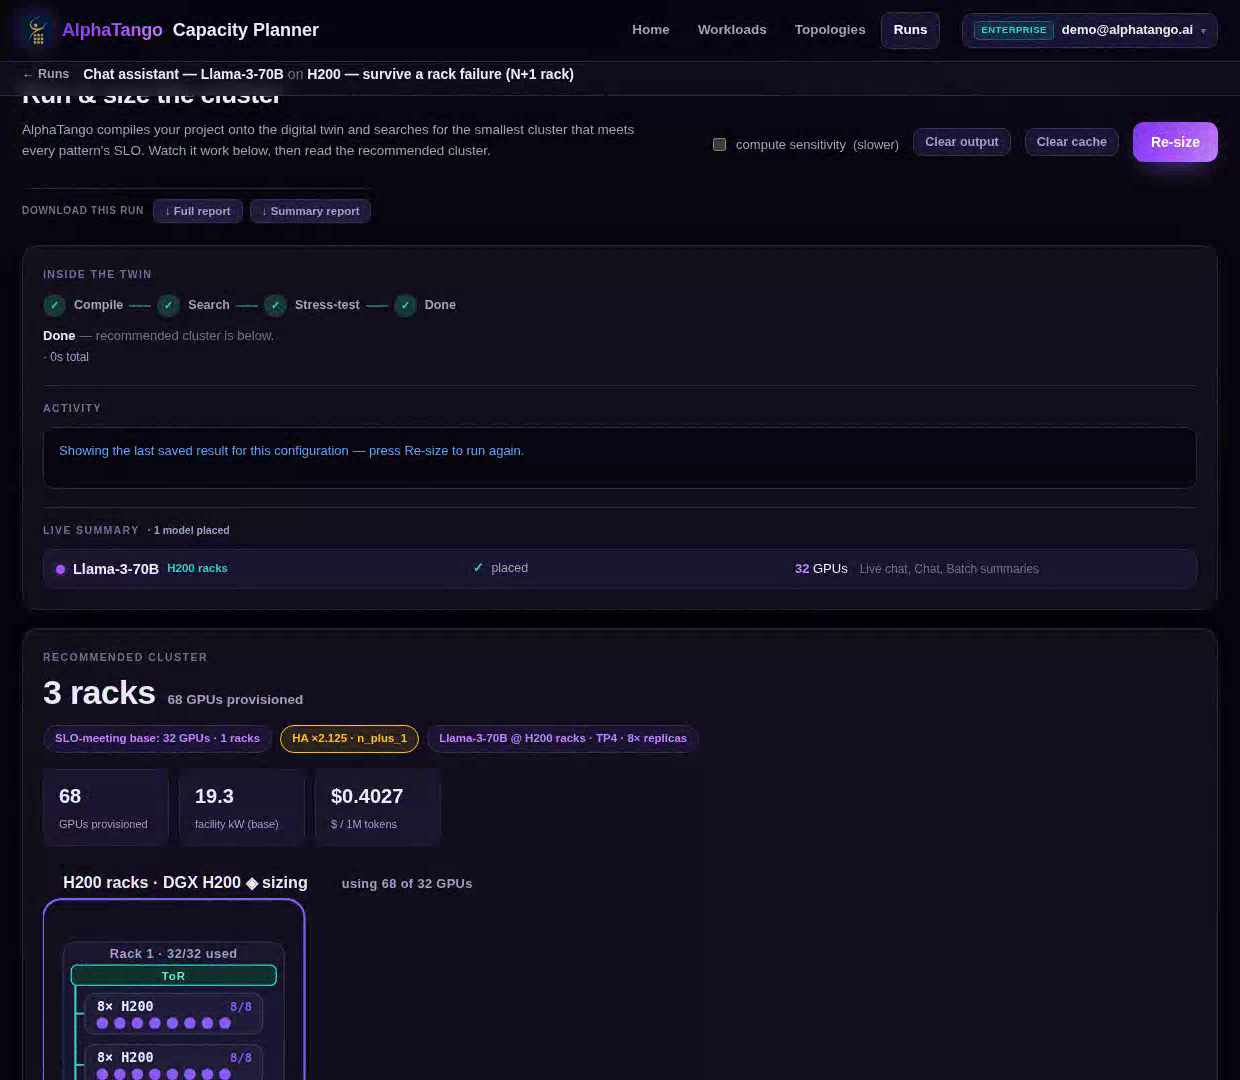
Base fleet: 32 GPUs, about $57,600 a month. Survive a server failure: 44 GPUs, about $79,200 (+38%). Survive a rack failure: 68 GPUs, about $122,400 — 2.1× the bill with no failure protection, because a whole spare 32-GPU rack stands by. Every speed promise met in all three.
02The Capacity Planner's report
Every run produces a report you can share: the workload, the recommended cluster, each traffic pattern against its speed promise, and the economics. This is the summary report from this demo, exactly as the Capacity Planner produced it.
03Watch
The demo in 34 seconds.
The real Capacity Planner screens, sped up.