What if my traffic doubles?
A Qwen3-32B support copilot on H200: 16 GPUs today. The Capacity Planner re-sizes it for growth: 24 GPUs at 1.5× the traffic, 36 at 2×. Doubling the traffic takes 2.25× the GPUs, not 2×.
Capacity Planner / demo 3
01What you enter, what you get
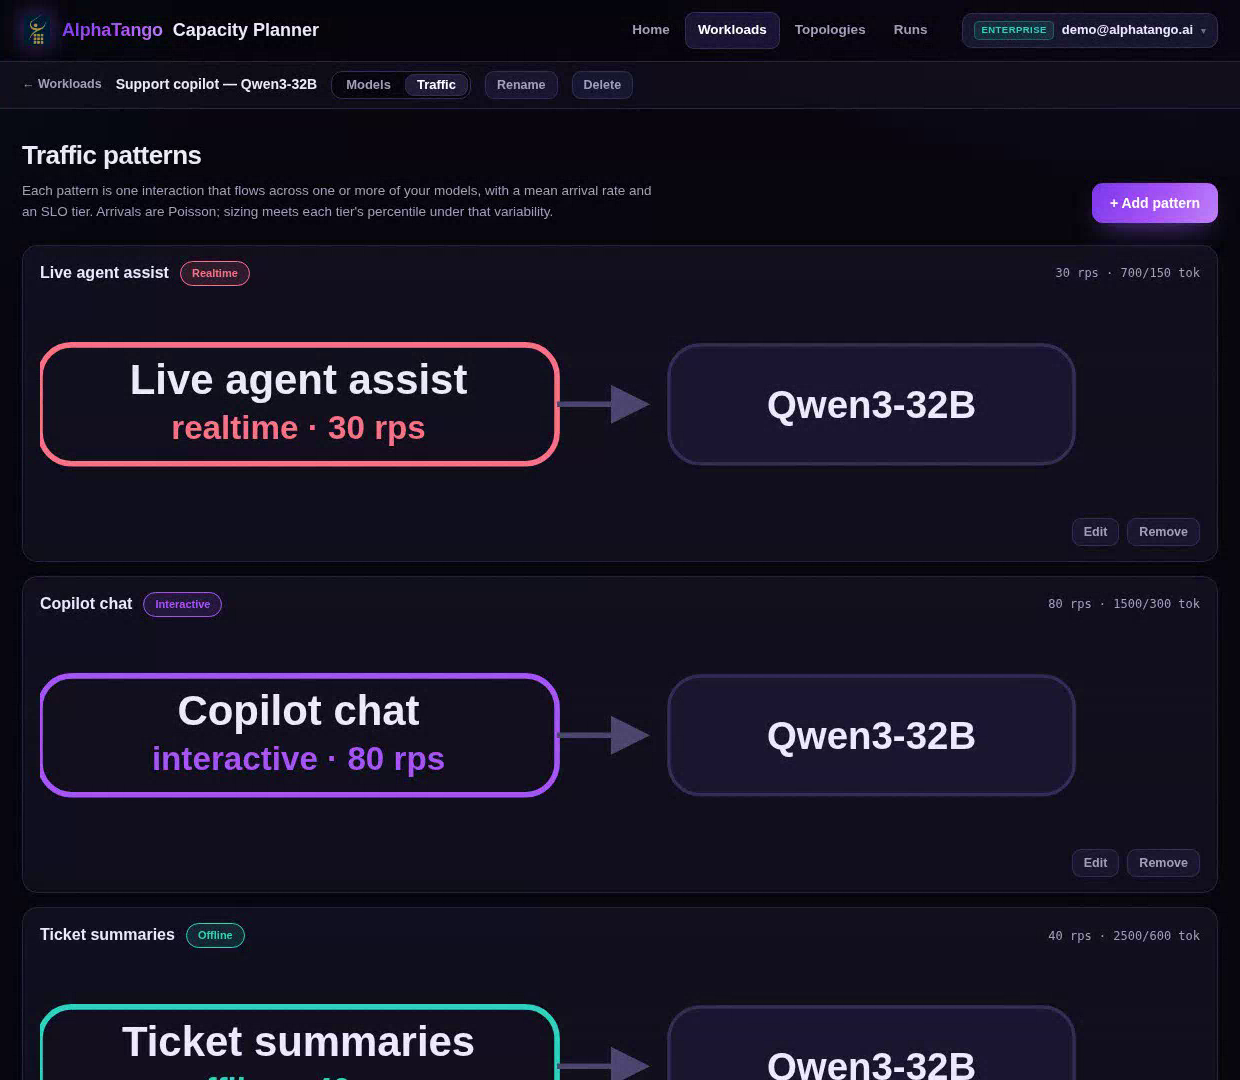
Qwen3-32B serving live agent assist (realtime promise), copilot chat and ticket summaries: 150 requests a second today. DGX H200 racks, with 'compute sensitivity' ticked so the Planner also sizes 1.5× and 2× the traffic.
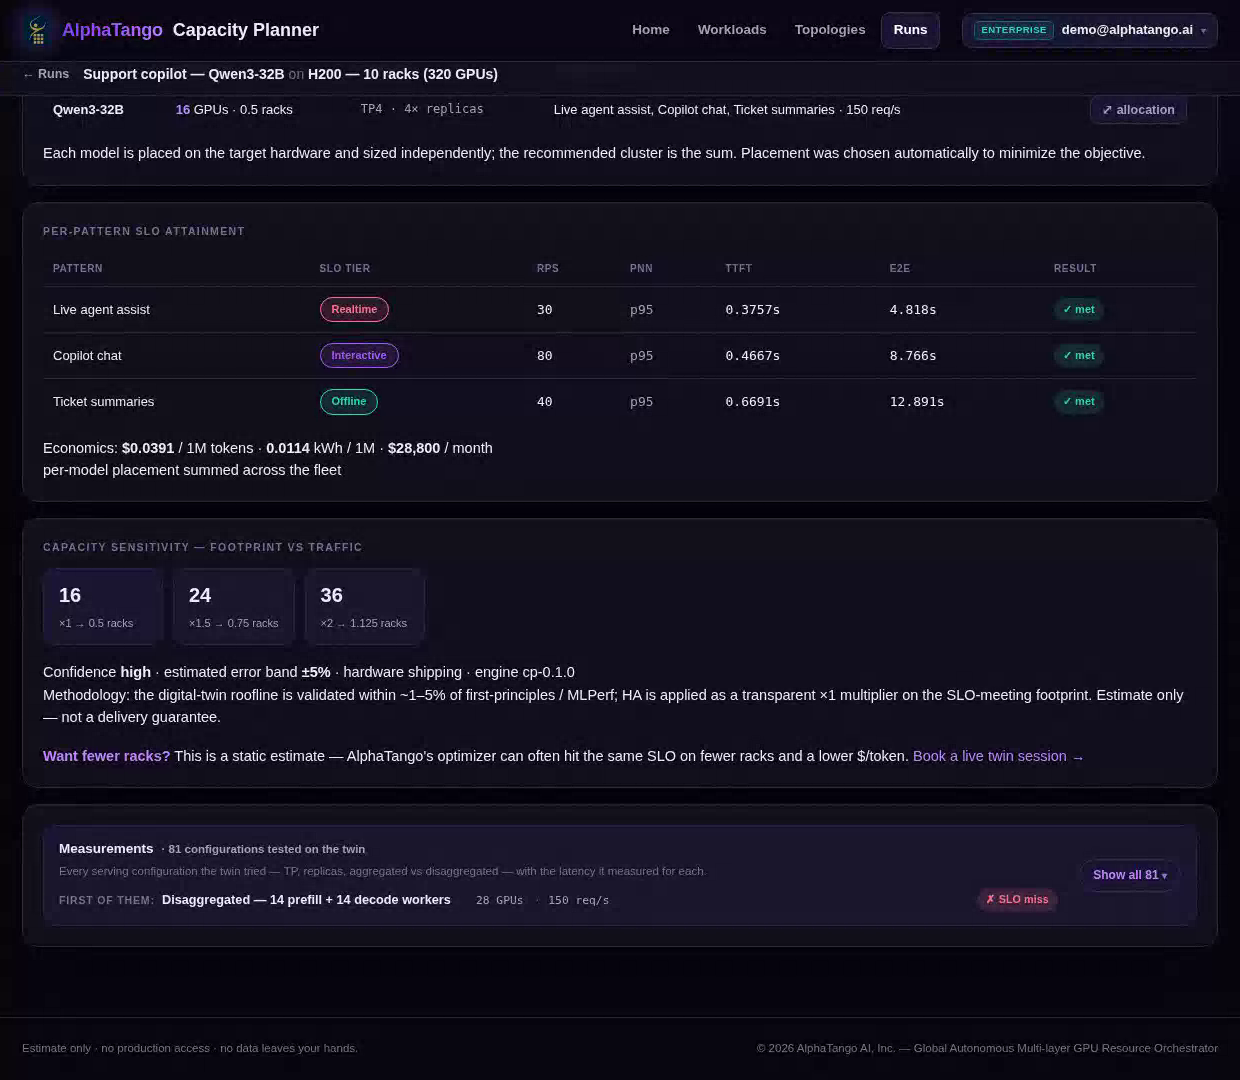
Today: 16 GPUs (4 copies of the model, 4 GPUs each), about $28,800 a month, every promise met. At 1.5× the traffic: 24 GPUs, about $43,200. At 2×: 36 GPUs, about $64,800 — 2.25× today's GPUs, because the realtime promise gets harder to keep as the copies fill up. Every promise met at every step.
02The Capacity Planner's report
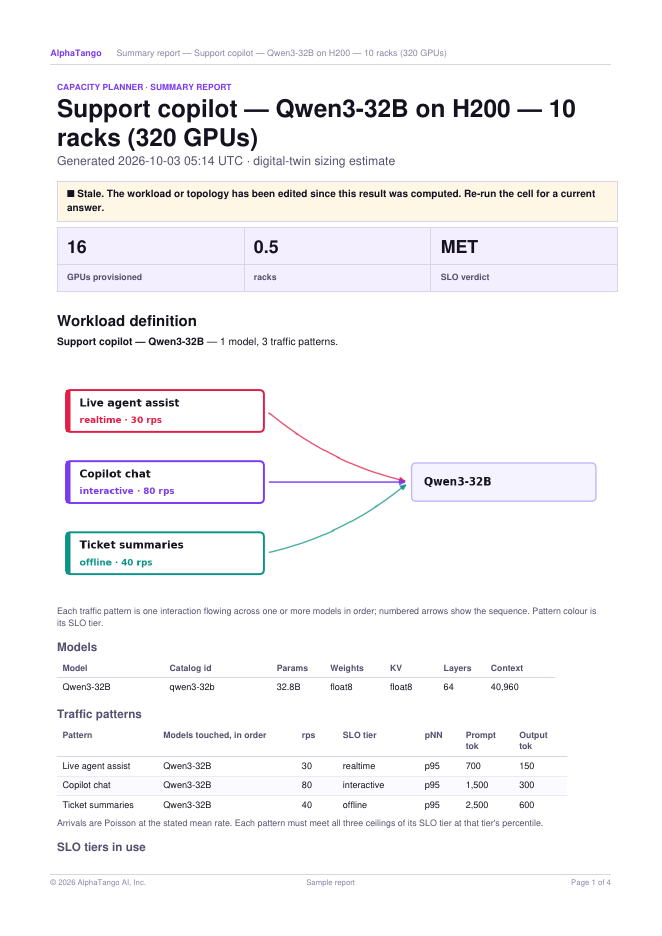
Every run produces a report you can share: the workload, the recommended cluster, each traffic pattern against its speed promise, and the economics. This is the summary report from this demo, exactly as the Capacity Planner produced it.
03Watch
The demo in 36 seconds.
The real Capacity Planner screens, sped up.