The GPU-limited startup: every setting explained.
A startup owns a fixed block of NVIDIA H200 GPUs and cannot get more this quarter. It runs a small and a medium open model (Qwen3-8B and Qwen3-32B) for chat, fast live chat, questions over documents and coding agents: 48 requests a second on average, with a daily peak 1.5 times the average. The GPUs are priced at rental rates to show what the same work would cost; for an owner, the gain shows up as more on-time answers from the GPUs it already has.
01Tool by tool
Factory settings vs AlphaTango.
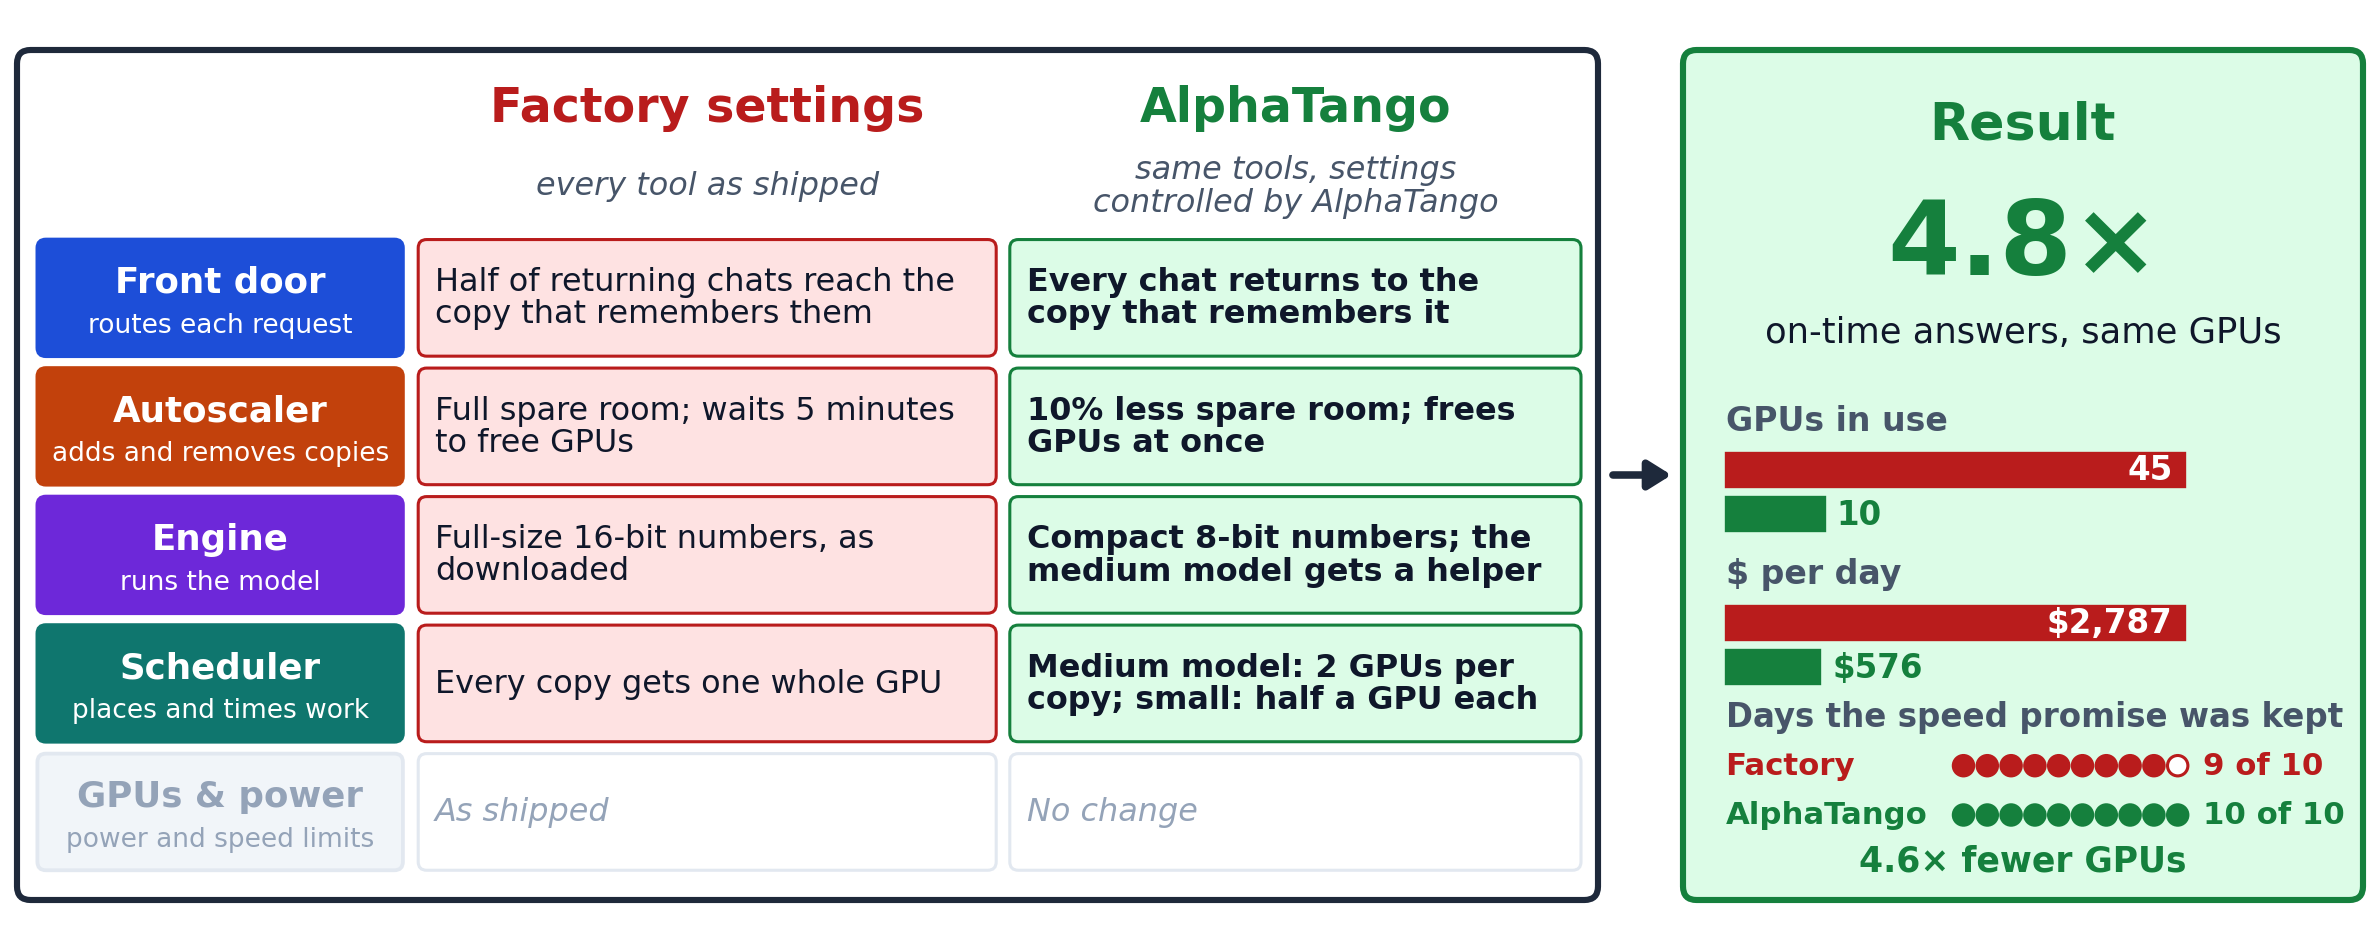
The same table as the diagram, with each setting explained. AlphaTango keeps every tool in place and controls only their settings, all tuned together for one goal for the whole service: the lowest cost per answer delivered within its speed promise.
| Tool | Factory settings (every tool as shipped) | AlphaTango (same tools, settings controlled by AlphaTango) |
|---|---|---|
| Front doorthe router that decides which copy of the model handles each request | Half of returning chats reach the copy that remembers themReturns about half of a conversation's turns to the copy that remembers it | Every chat returns to the copy that remembers itReturns every turn to that copy; agent memory kept for 5 minutes between turns |
| Autoscaleradds and removes copies of the model as traffic changes | Full spare room; waits 5 minutes to free GPUsFull margin of spare room; waits 5 minutes to release a GPU | 10% less spare room; frees GPUs at onceAbout 10% less spare room, because each copy now carries more; releases idle GPUs at once |
| Enginethe serving engine that runs the model on the GPUs | Full-size 16-bit numbers, as downloaded16-bit numbers, as downloaded | Compact 8-bit numbers; the medium model gets a helper8-bit numbers for both models and their conversation memory; drafting helper on for the medium model |
| Scheduler & GPU managerdecides where copies run, how many GPUs each gets and when batch work runs | Every copy gets one whole GPUOne whole GPU per copy | Medium model: 2 GPUs per copy; small: half a GPU eachMedium model: 2 GPUs per copy, so long prompts finish in time; small model: each GPU split into two halves |
| GPUs & powerGPU power limits and clock settings | As shipped | No change |
02Where factory settings fall short
Why the factory set-up costs more.
Each tool runs with its vendor’s default settings and knows nothing about the others. Where that falls short in this case:
Both models keep the 16-bit numbers they were downloaded with, so most of each GPU's memory is taken up by the model and its conversation memory rather than by useful work.
Each copy of a model sits on one whole GPU, even the small model, which needs only part of one; the medium model gets no more than one GPU, so long prompts finish slowly.
The autoscaler keeps a full margin of spare room and waits five minutes before letting a GPU go.
The work averaged 45 GPUs ($2,787 a day at rental prices) and still missed the speed promise on 1 of 10 unseen days. Most of those GPUs were holding memory, not doing work.
03Whole-Service Gate
Kept only if the whole service improved.
✓ The gate for this case
A version with no safety margin was 81% cheaper but kept the promise on only 6 of 10 days. The Whole-Service Gate rejected it and kept the 79% version, which kept the promise on 10 of 10.
Every candidate change is tested on the AlphaTango Digital Twin, on traffic days the settings had never seen.
04Result
4.8× the on-time answers from the same GPUs
for an owner, the headline
45 down to 10 on a daily average
79% cheaper per on-time answer
against 9 of 10 at factory settings
'3.4× fewer GPUs' compares GPUs switched on, averaged over the day. 'Lower cost per on-time answer' divides what the whole service costs (GPU rental plus electricity) by the work it delivered within its speed promise. Both compare AlphaTango with every tool left at the settings its vendor ships (factory settings). Results come from AlphaTango's whole-system simulator, built on its Digital Twin and run on public traffic recordings, scored on days the settings had never seen. GPU prices are rental list prices.