The GPU-limited startup
Can't get more GPUs this quarter? AlphaTango frees the ones you have. In our simulation, a startup's work dropped from 45 GPUs to 10, 4.6× fewer: 4.8× the on-time answers from the same GPUs.
Case 06 / Startups
01Before / after
Showcase Search simulation, 10 unseen days, two open models on NVIDIA H200 GPUs. 4.8× = 79% lower cost per on-time answer.
02How AlphaTango wins
Local settings. Global goal.
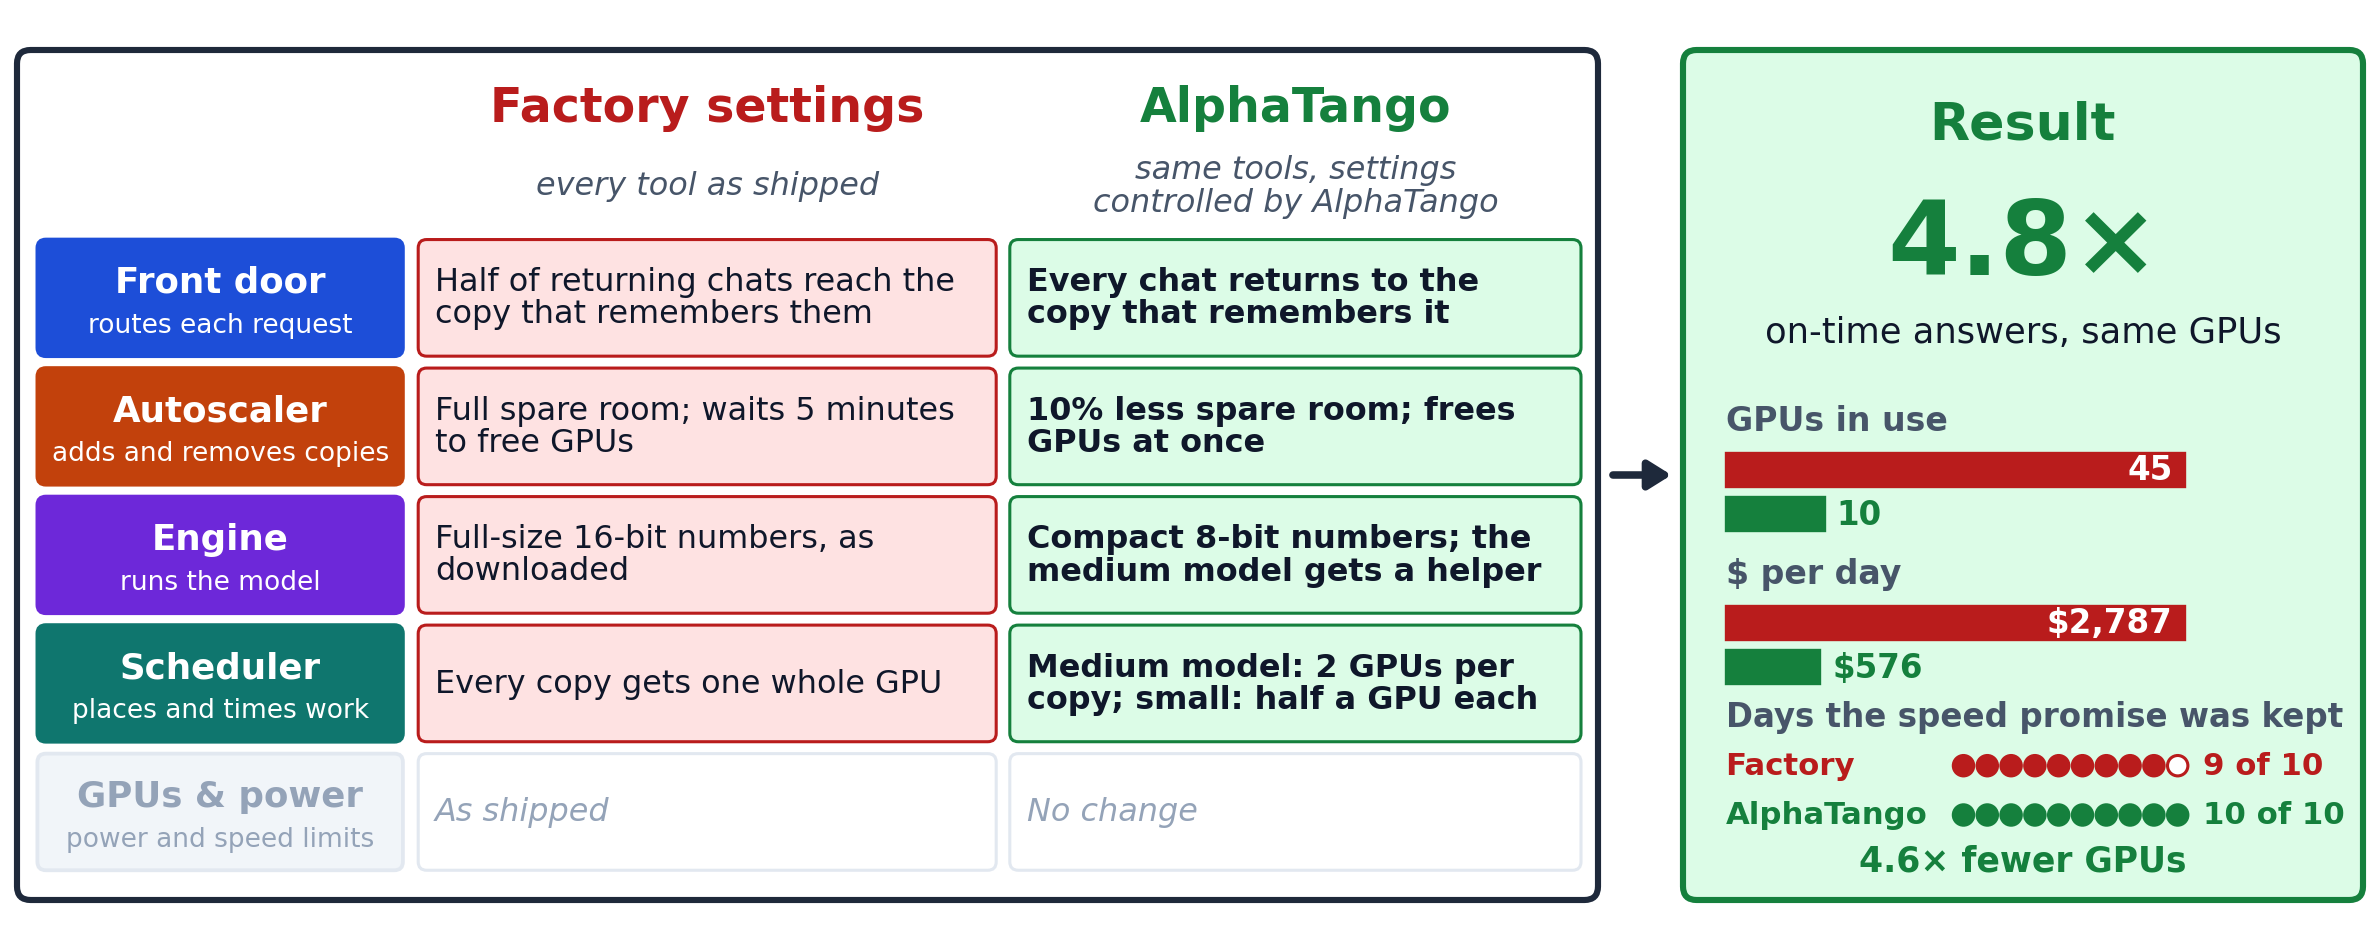
Left: what every tool does at the settings its vendor ships. Middle: the settings AlphaTango changed, tool by tool, each kept only because the whole service got better. Right: the result.
03The story
4.8× the on-time answers from the same GPUs
For: Startups, research labs and internal platforms that cannot get more GPUs this quarter.
The situation
A startup owns a fixed block of NVIDIA H200 GPUs and cannot get more this quarter. It runs a small and a medium open model for chat, fast live chat, questions over documents and coding agents: 48 requests a second on average, with a daily peak 1.5 times the average. At factory settings its work used 45 GPUs on average and still missed the speed promise on 1 of 10 days. Most of those GPUs were holding memory, not doing work.
What AlphaTango does
AlphaTango stores the models with fewer bits, gives the medium model two GPUs per copy and splits the small model's GPUs in half, then tells the autoscaler that each copy now carries more and has the front door send every conversation back to the copy that remembers it. Changed alone, any one of these just moves the bottleneck to the next tool.
The proof
On 10 unseen days the same work needed 10 GPUs instead of 45 (4.6× fewer), at 4.8× lower cost per on-time answer (79% less), and the promise kept on 10 of 10 days, against 9 of 10 for factory settings. For an owner, that is 4.8× the on-time answers from the same GPUs. A cheaper version was rejected because it kept the promise on only 6 of 10 days.
Next step
If you cannot buy more GPUs, let us free the ones you have. Send us a day of traffic to start.
The GPUs are priced at rental rates ($2,787 a day down to $576) to show what the same work would cost. Without the fewer-bits change, AlphaTango is still 54% cheaper, with the promise kept on 10 of 10 days.
04Watch
The case in 37 seconds.
Narrated walk-through of the situation, what AlphaTango changes and the result.