AI coding agents
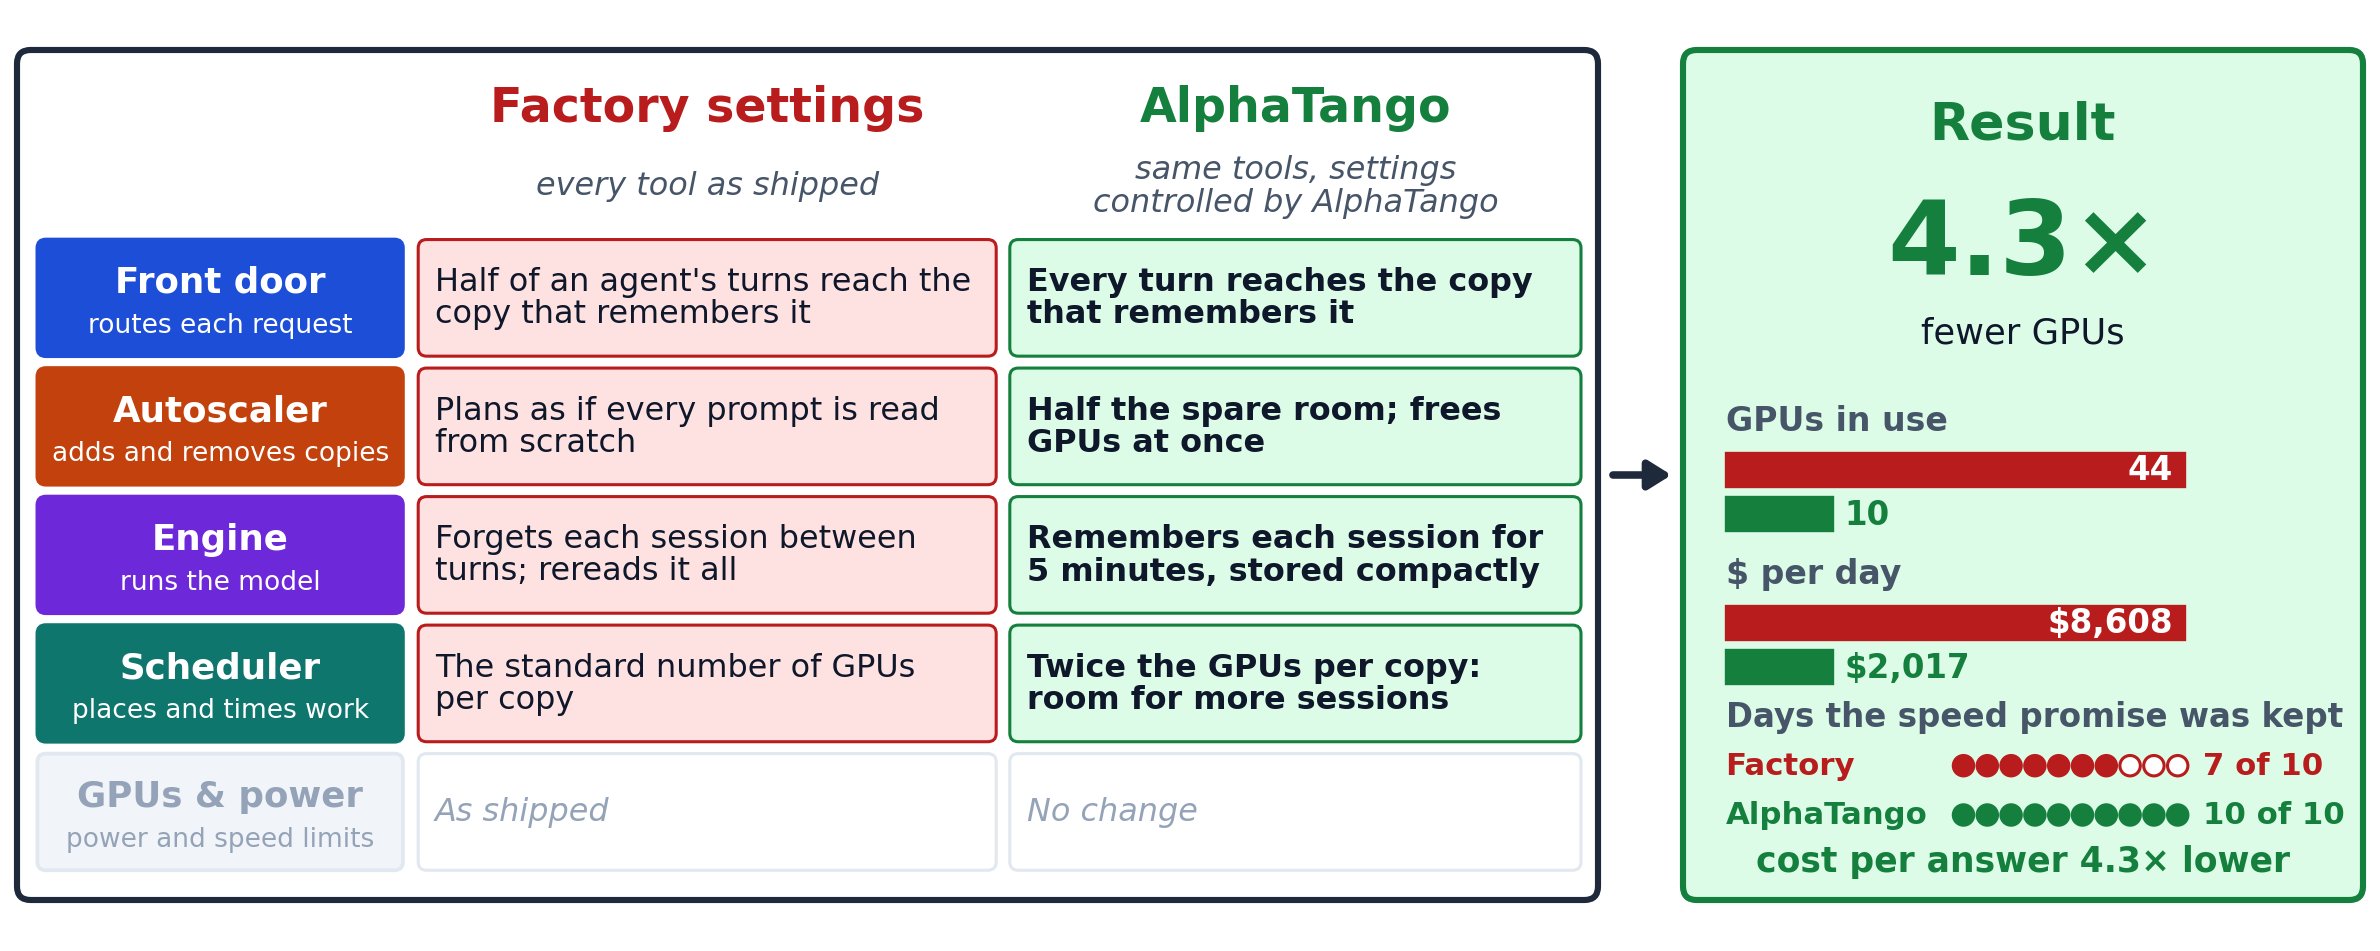
Coding agents resend a long prompt every turn, about 25,000 tokens, mostly repeated. AlphaTango keeps each session's work on the right copy of the model and tells the autoscaler: 44 GPUs down to 10, 4.3× fewer, at 4.3× lower cost per on-time answer.
Case 03 / Coding agents
01Before / after
Simulation at 2026 prompt lengths, 10 unseen days, against a fairly sized factory baseline. 4.3× = 77% lower cost per on-time answer.
02How AlphaTango wins
Local settings. Global goal.
Left: what every tool does at the settings its vendor ships. Middle: the settings AlphaTango changed, tool by tool, each kept only because the whole service got better. Right: the result.
03The story
4.3× fewer GPUs: 44 down to 10
For: Companies running coding assistants and AI agents with long, repetitive prompts.
The situation
A coding-agent company runs multi-turn agent sessions over large code repositories on a very large model. Each turn sends about 25,000 tokens (word pieces) of code and context, at 2026 lengths, and most of it repeats the turn before. At factory settings the engine throws a session's working notes away between turns, the front door sends a turn back to the copy that remembers it only half the time, and the autoscaler plans capacity as if nothing were ever reused.
What AlphaTango does
AlphaTango keeps each session's working notes between turns, stores them in a more compact form where quality allows, and sends every turn back to the copy of the model that holds them. It also tells the autoscaler how much rereading this saves, so the saving shows up as a smaller bill.
The proof
Against factory settings given the smallest fleet that kept the promise on a practice day, scored on 10 unseen days: 4.3× fewer GPUs (44 down to 10), 4.3× lower cost per on-time answer (77% less), $8,608 a day down to $2,017, and the promise kept on 10 of 10 days, against 7 of 10 for factory settings. Against factory settings as shipped: 5.3× lower cost. On real 2026 production traffic: 3.2× to 3.8× lower cost, with the promise kept on 4 of 4 days.
Next step
Send us a day of agent traffic, and we will show you how much of your fleet is rereading the same code.
Without the fewer-bits change, AlphaTango is still 61% cheaper, with the promise kept on 10 of 10 days.
04Watch
The case in 38 seconds.
Narrated walk-through of the situation, what AlphaTango changes and the result.
05More use cases