Many models, one pool
Most internal models are used only a few times an hour, yet each one holds its own GPUs. AlphaTango pools the quiet ones and keeps every speed promise: in the best case, 122 GPUs down to 13, 9.3× fewer.
Case 04 / Many models
01Before / after
Simulation on the popularity pattern of real 2026 production traffic, 61 models, 4 unseen days. 9.3× fewer GPUs; 9.8× lower cost per on-time answer.
02How AlphaTango wins
Local settings. Global goal.
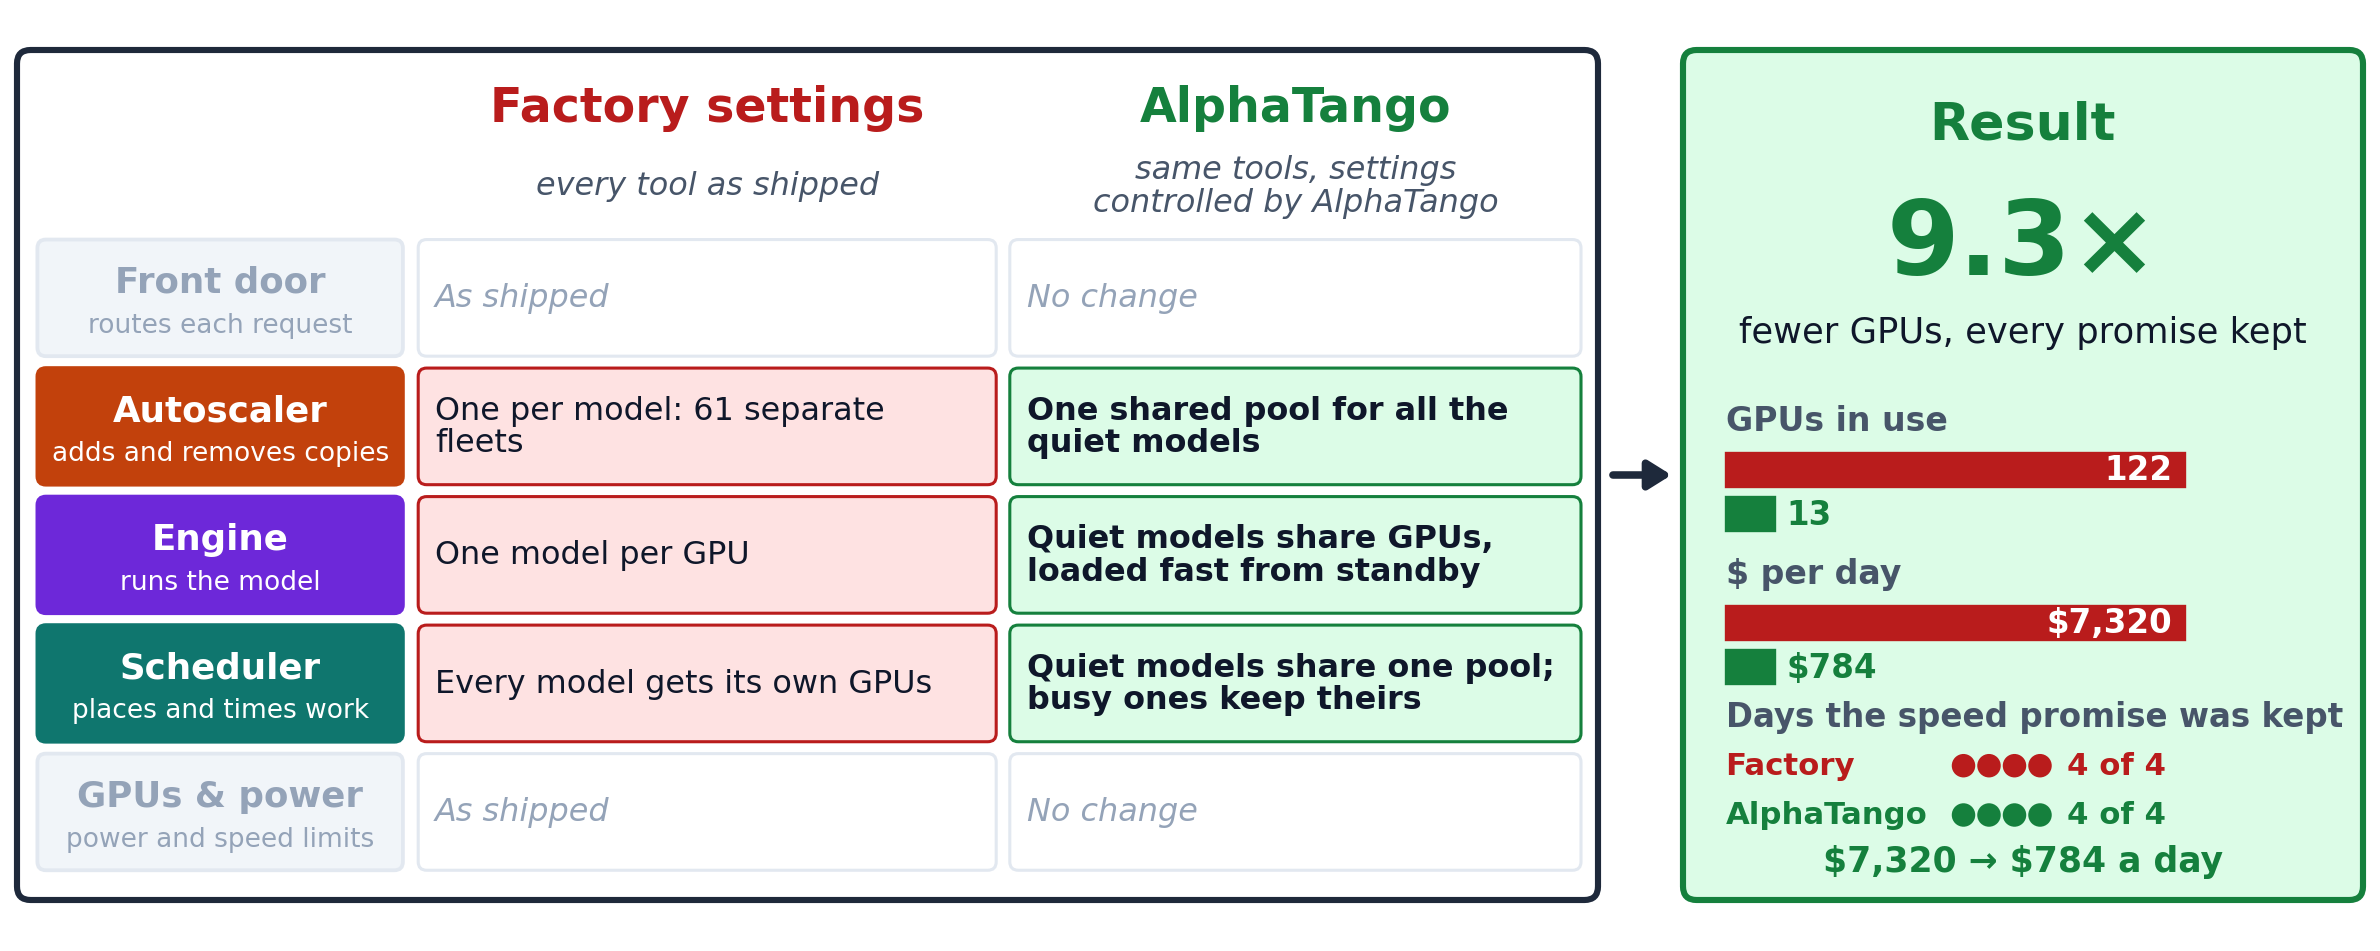
Left: what every tool does at the settings its vendor ships. Middle: the settings AlphaTango changed, tool by tool, each kept only because the whole service got better. Right: the result.
03The story
9.3× fewer GPUs: 122 down to 13
For: Enterprises and platforms running many fine-tuned or specialist models.
The situation
An enterprise runs 61 internal models. A few are busy; most are used only a few times an hour. At factory settings every model gets its own GPUs and its own autoscaler, so most of the fleet sits idle, paid for all day.
What AlphaTango does
AlphaTango places the rarely used models in one shared pool of GPUs, lets them share each GPU and load in from standby memory when needed, and lets one autoscaler decide how many GPUs the pool needs. Busy models keep their own GPUs, so every model still keeps its speed promise. Placement, model loading and GPU count are tuned together.
The proof
In the best case: 9.3× fewer GPUs (122 down to 13), $7,320 a day down to $784, and 9.8× lower cost per on-time answer (90% less), with every promise kept on 4 of 4 unseen days. A typical situation from the same search was 4× cheaper, and there factory settings broke the promise on all 4 days. Hosting many customers' fine-tuned variants is a related case: factory settings could not keep the promise at any fleet size, while AlphaTango was 2.1× to 2.8× cheaper and kept it.
Next step
List your models and how often each is used, and we will show you how many GPUs they really need.
The 89% is the best realistic point of the search; on real 2026 production traffic, re-tuned, the saving was 34%.
04Watch
The case in 34 seconds.
Narrated walk-through of the situation, what AlphaTango changes and the result.