The hidden fleet
A large-model API with a sharp daily peak, every tool at factory settings: 265 GPUs on average, and real-time answers still late every afternoon. AlphaTango tunes the whole service together: 79 GPUs, promise kept every day. 3.4× fewer.
Case 01 / API at scale
01Before / after
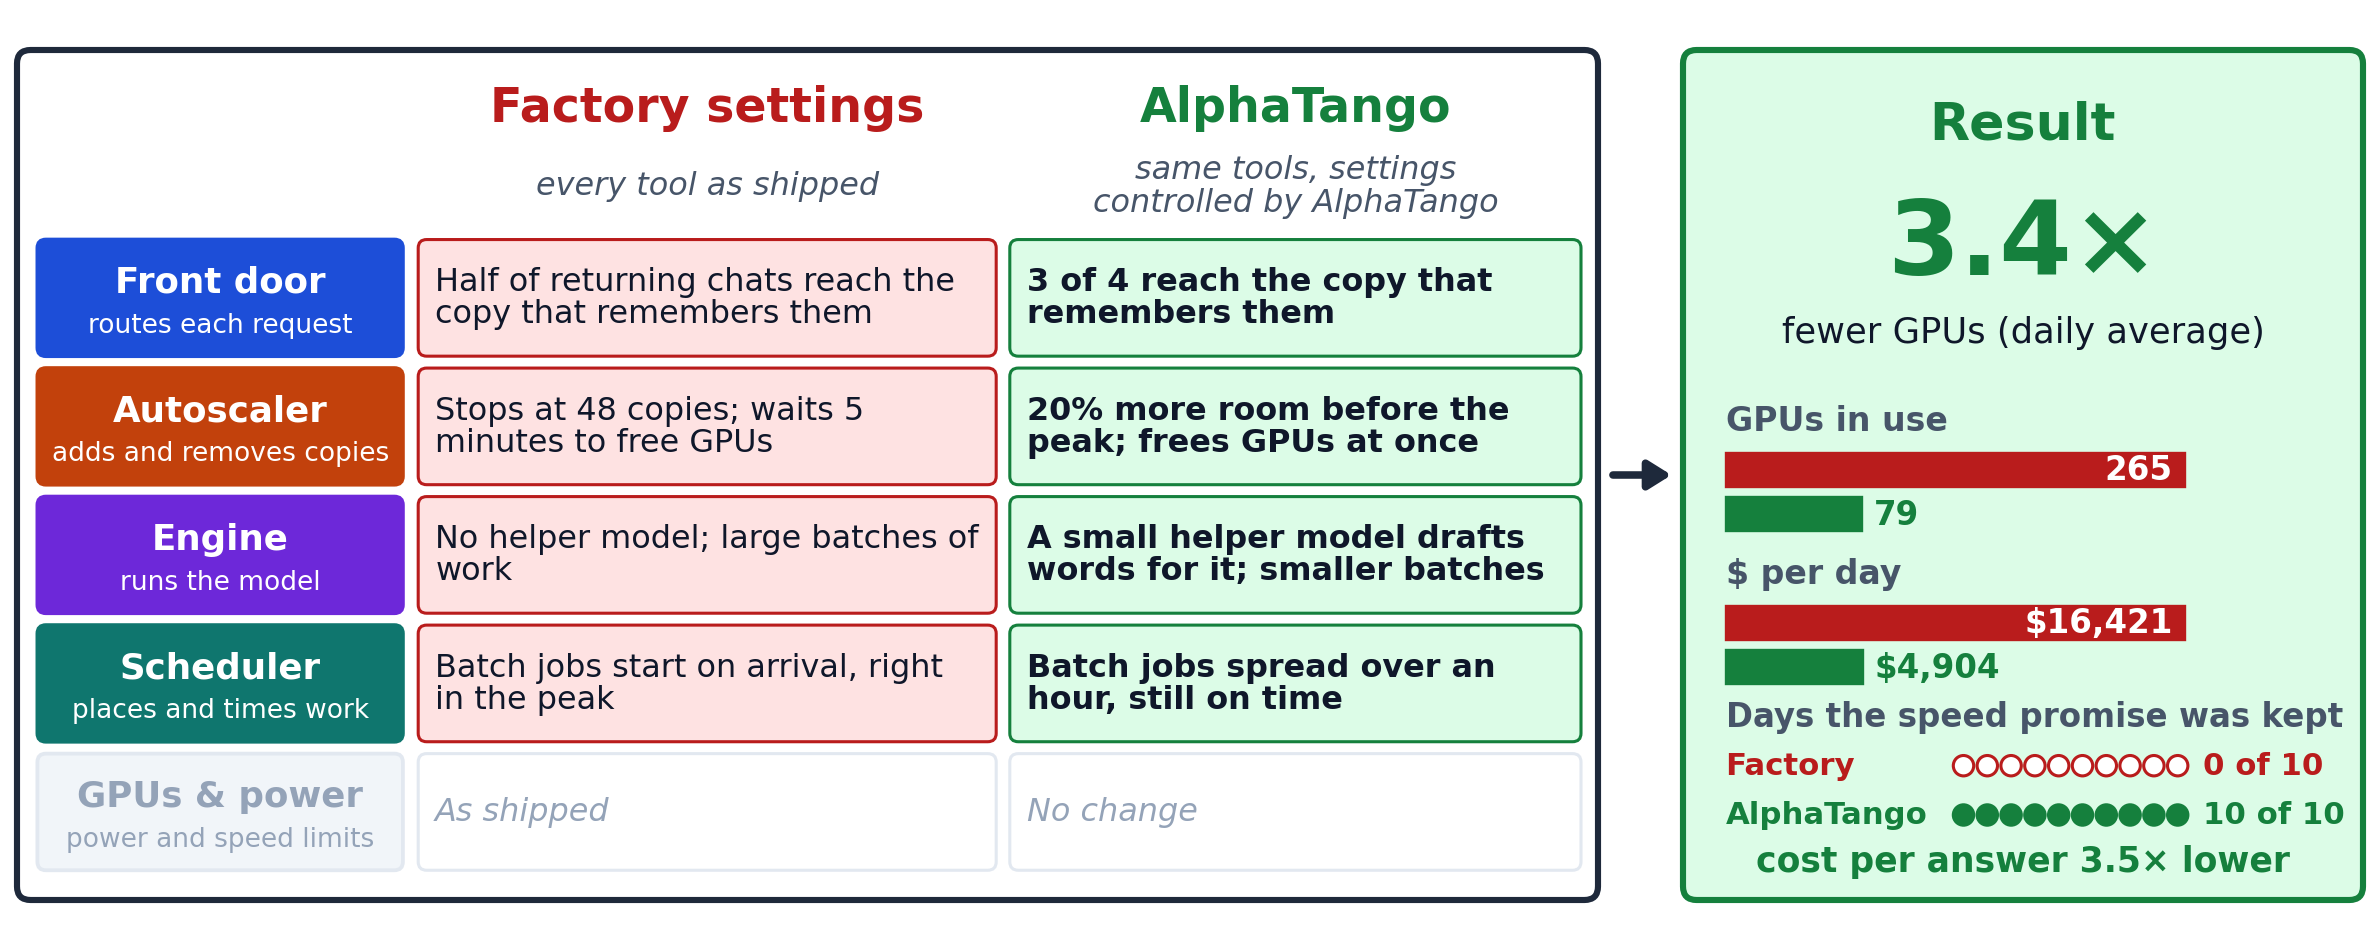
Showcase Search simulation, 10 unseen days; GPUs averaged over the day. 3.5× = 71% lower cost per on-time answer. Factory autoscaler limited to 48 copies of the model.
02How AlphaTango wins
Local settings. Global goal.
Left: what every tool does at the settings its vendor ships. Middle: the settings AlphaTango changed, tool by tool, each kept only because the whole service got better. Right: the result.
03The story
3.4× fewer GPUs: 79, not 265
For: AI API providers and large internal platforms running a big model with a sharp daily peak.
The situation
An AI provider serves a very large model (DeepSeek-V3 on rented NVIDIA H200s) for many kinds of work: chat, real-time chat, reasoning, coding agents and batch jobs. 241 requests a second, with a daily peak about three times the average. At factory settings it uses 265 GPUs on average over the day, and real-time answers still run late every afternoon.
What AlphaTango does
AlphaTango sets the whole service together, in its Digital Twin, for one goal: the lowest cost per answer delivered on time. The engine gets a drafting helper and smaller work batches. The autoscaler keeps 20% more spare room but releases GPUs at once. Batch work is spread over 60 minutes inside its 4-hour window instead of landing on the peak. The front door sends more returning turns to the copy that already remembers them. No single tool would choose these settings on its own; together they shrink the fleet.
The proof
In our Showcase Search simulation, on 10 days of traffic the settings had never seen, factory settings averaged 265 GPUs over the day and kept the promise on 0 of 10 days. AlphaTango averaged 79 GPUs, 3.4× fewer, kept it on 10 of 10, and cost 3.5× less per on-time answer (71% less): about $11,500 a day at rental prices.
Next step
Send us a day of your traffic, and we will show you the fleet you are really paying for.
Factory settings ran with an autoscaler limit of 48 copies of the model (384 GPUs). At the afternoon peak they needed about twice that and missed the promise. Without the limit they would need 354 to 424 GPUs and still miss it on some days. Both 265 and 79 are GPUs switched on, averaged over the day, from AlphaTango's Showcase Search simulation.
04Watch
The case in 36 seconds.
Narrated walk-through of the situation, what AlphaTango changes and the result.
05More use cases