Twice the AI from the GPUs you already own
You own a fixed fleet and demand keeps growing. AlphaTango tunes the whole stack for one goal, the most on-time work from the GPUs you have. In our simulation, 400 GPUs did the work of about 816: 2× the useful work.
Case 05 / Fixed fleets
01Before / after
Simulation of a 400-GPU owned fleet: 2.04× the useful work; matching it at factory settings would take about 416 more GPUs.
02How AlphaTango wins
Local settings. Global goal.
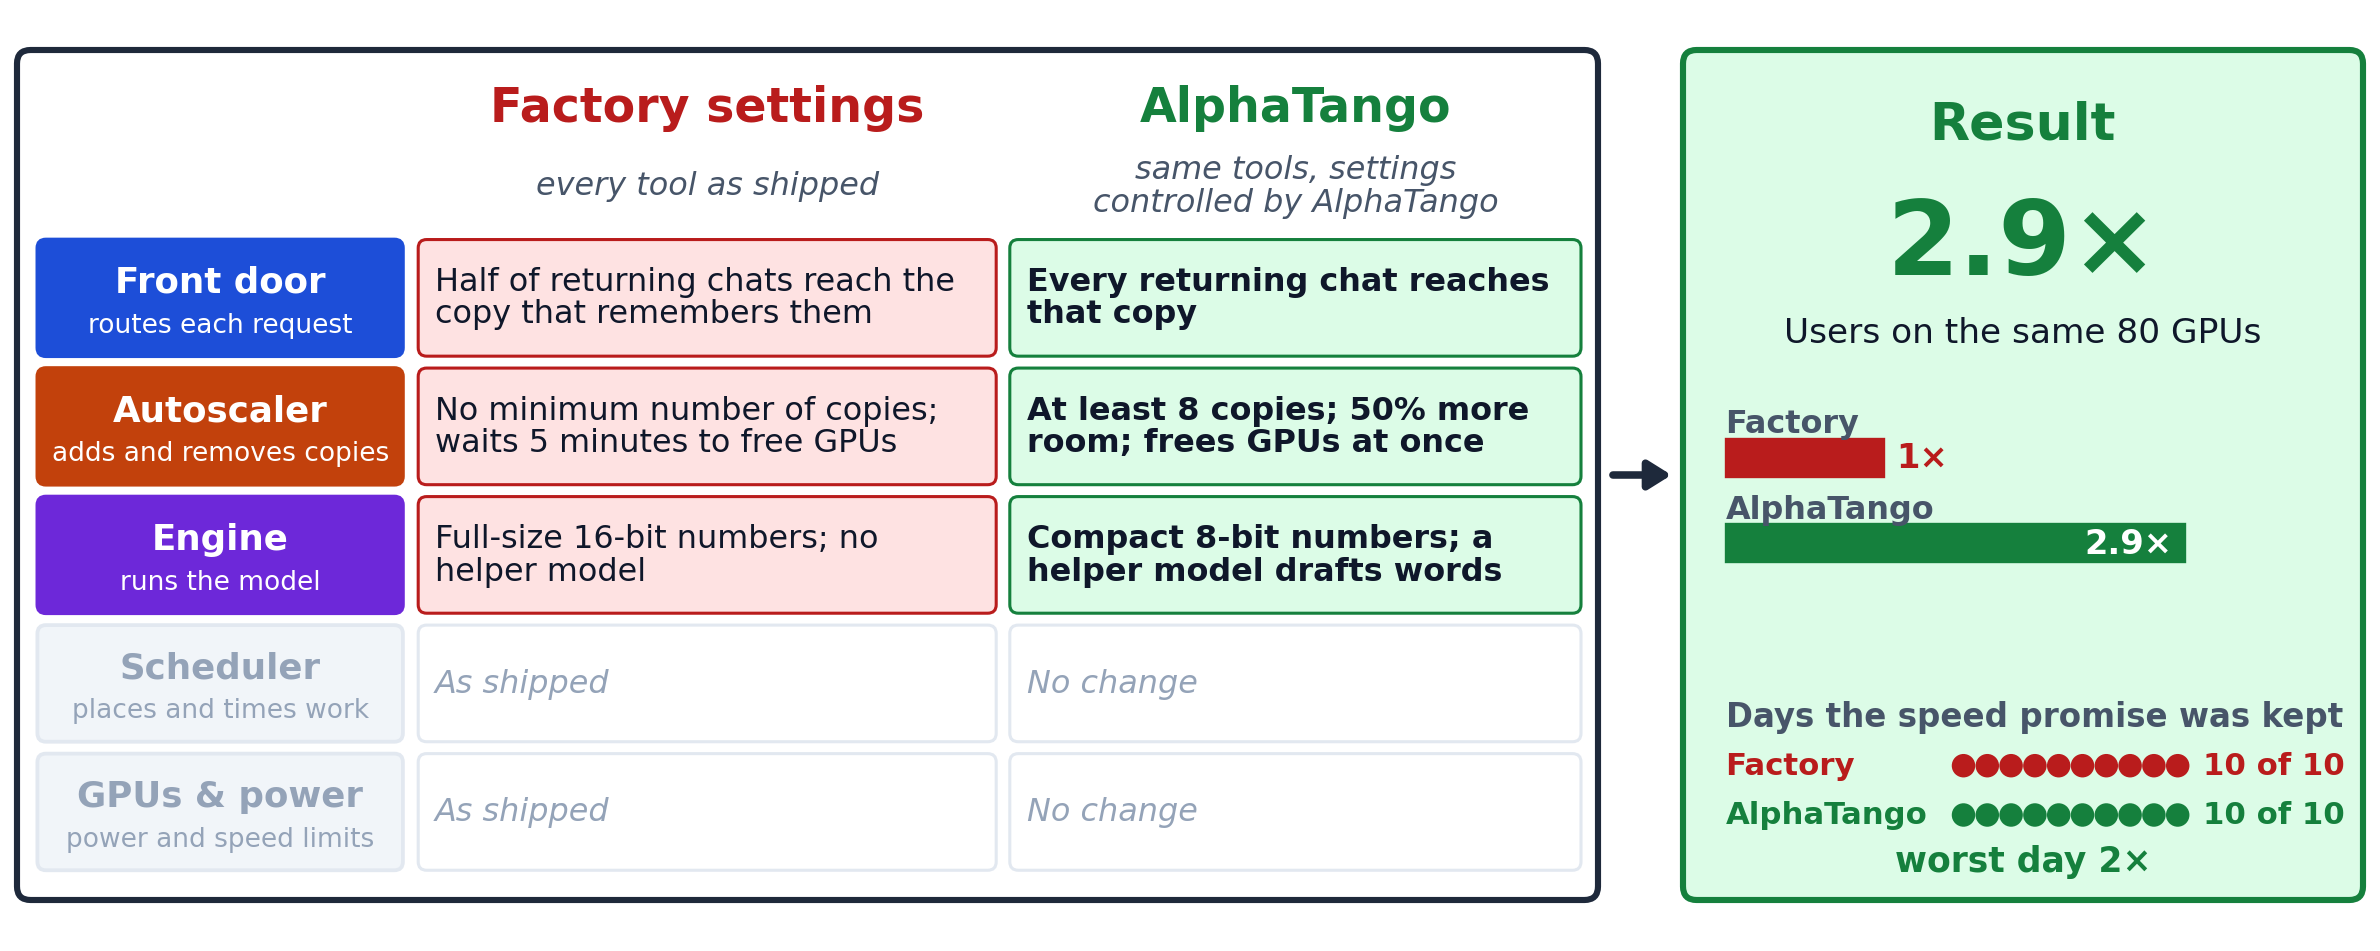
Left: what every tool does at the settings its vendor ships. Middle: the settings AlphaTango changed, tool by tool, each kept only because the whole service got better. Right: the result.
03The story
2× the useful work from the same 400 GPUs
For: Operators with a fixed fleet who cannot simply buy more GPUs or more power.
The situation
A national or enterprise operator owns a fixed fleet of 400 GPUs: chat and document assistants, overnight batch work and a block of high-density GPU racks. It has more demand than capacity and cannot simply buy more GPUs or more power. At factory settings each tool optimizes its own corner, and the fleet delivers far less useful work than it could.
What AlphaTango does
AlphaTango tunes the whole stack for one goal, the most on-time work from the GPUs you have. How each model runs, how memory is used, where work is placed, when batch work runs and how many GPUs each service gets are all set together, and re-tuned as demand changes.
The proof
The same 400 GPUs carry 2× the useful work (104% more); matching that at factory settings would take about 416 more GPUs. On a single 80-GPU site: 2.9× the users, with the promise kept on 10 of 10 unseen days, and still 2× on the worst day.
Next step
Tell us what your fleet runs today, and we will show you how much more it can carry.
Each owned fleet was set at exactly what fairly sized factory settings need at their peak.
04Watch
The case in 34 seconds.
Narrated walk-through of the situation, what AlphaTango changes and the result.